🌈 (Alt)Autonomy is a spectrum, not a switch
Right-size the model, right-size the autonomy, and keep the people who can tell the difference.
Steven B Miers · October 15, 2026 · v1.01
📝 Introduction
Earlier this year I watched a team ship a project they’d generated end to end with an AI assistant. They’d given it an opinionated database schema with full referential integrity, a matching OpenAPI spec, and a proprietary spec of business rules.
It worked on day one. It was also, in effect, one big object: the request handler parsed the input, validated it, queried the database, built the response and sent the notification, and every piece reached into the guts of every other piece to do it. The first change request, a second notification channel, couldn’t be made without touching all of it. The generated tests checked the implementation instead of the behavior, so they broke too. In the end, the one person on the team who could see why rewrote the feature by hand.
The code was never wrong. It was plausible, it passed, and it was welded together so tightly that nothing could move.
I don’t blame the tool. It did what it was asked. Nobody in the loop knew what to ask for, or that it mattered.
🧭 Where I’m standing
I use AI every day: for research, for learning, for keeping my old Land Rover running, for code, and for running half-baked designs past it before I inflict them on humans. So this is no bash on AI, and I’m not shouting at clouds. (Not those clouds, anyway.) I’ve trained and shipped production neural networks since 2007, including a patented behavioral-prediction platform, NLP pipelines with custom-trained language models, and a human-in-the-loop curation system that fed corrections back into training. More recently it’s been LLM-based systems and the agents built on them. I understand how these things work as math I’ve had to implement, not as a slogan.
Which is why one current habit worries me: reach for the biggest LLM for every problem, run it as autonomously as the demo allows, and treat the people who can tell good output from plausible output as overhead.
⚖️ Judgment
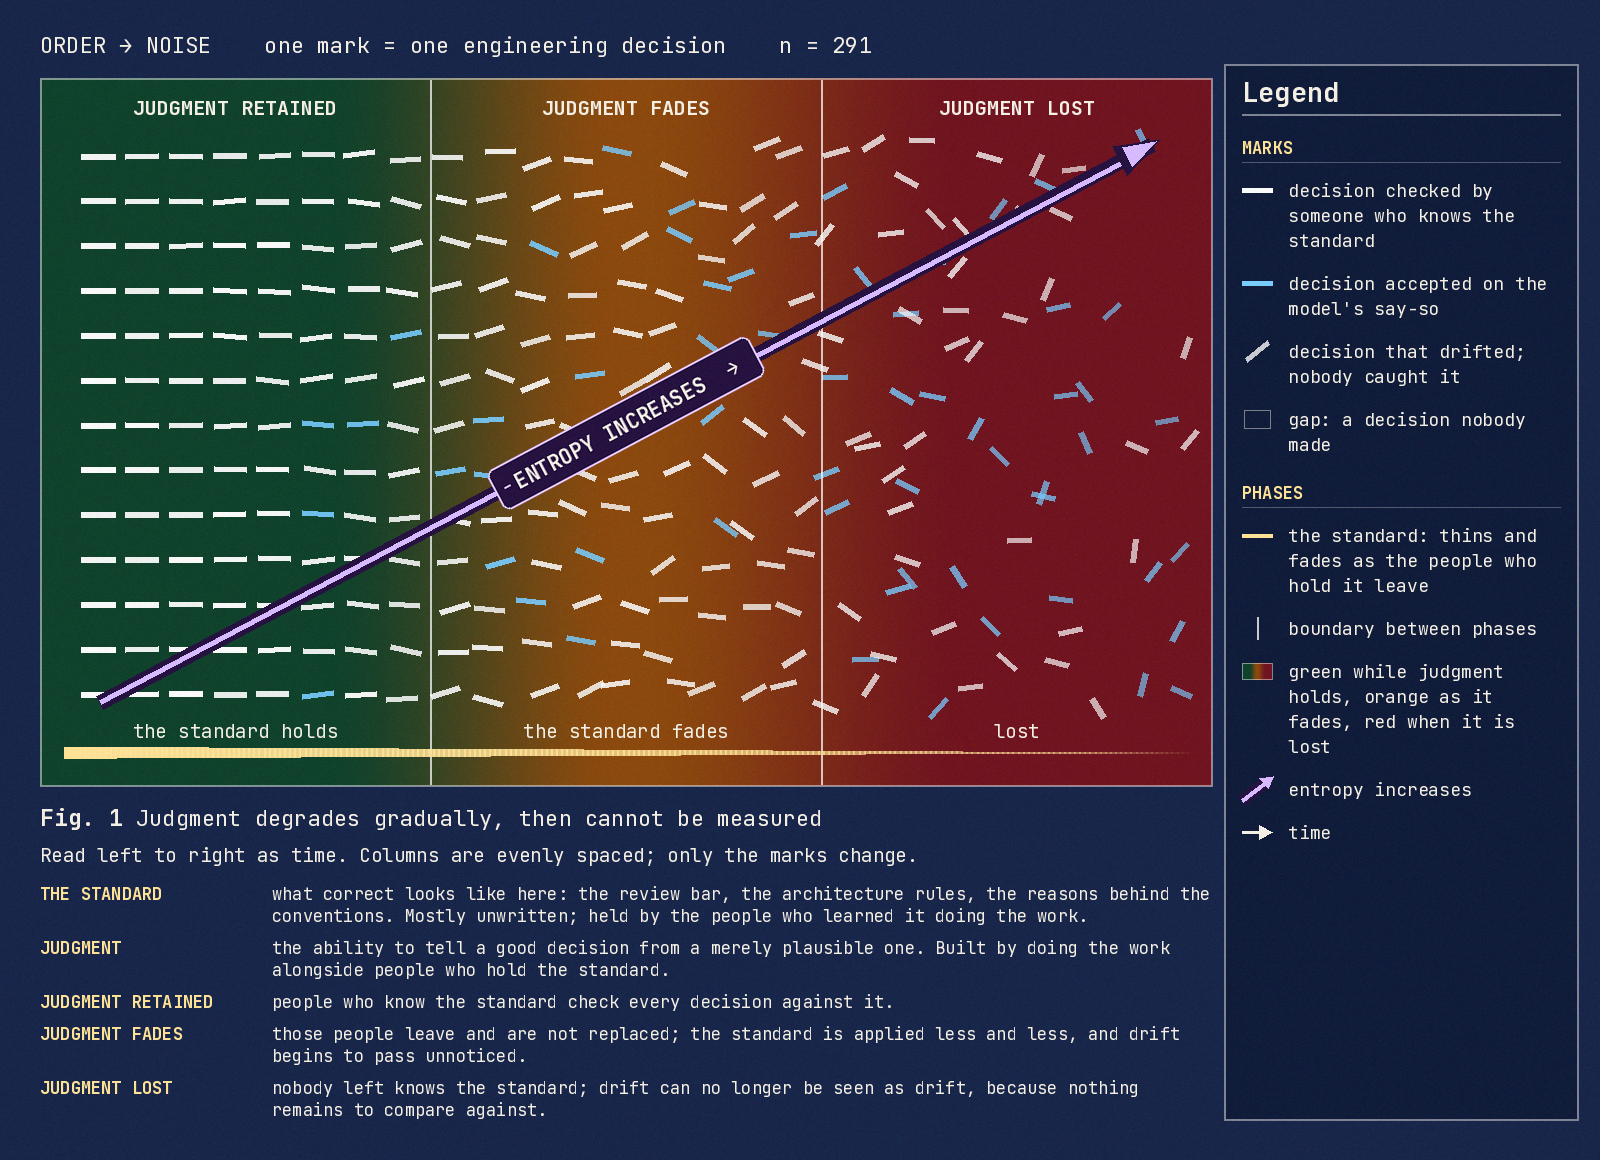
Fig. 1: Judgment degrades gradually, then can’t be measured. Read it as time passing: experienced engineers leave, and the junior pipeline that would have replaced them gets cut. Judgment is the ability to tell a good decision from a merely plausible one, and you only build it by working next to people who hold the standard.
The measurements don’t back the habit. METR’s 2025 randomized trial found experienced developers took 19% longer with AI on their own codebases, and afterward believed they’d been 20% faster. Stack Overflow’s 2025 survey put trust in AI accuracy at 29%, and 66% of developers named answers that are almost right as their top frustration. In Anthropic’s own trial, developers who learned a new library with AI scored 50% versus 67% on a comprehension quiz taken without it. I wouldn’t hang a policy on any single study, but they all point the same way, and that’s what bothers me.
📜 Coding was never the hard part
Writing code isn’t software engineering. The hard part is knowing what to build, what to leave out, what breaks at 3 a.m., and which requirement the customer forgot to mention. Programming languages exist because English is a terrible specification language, and a spec complete enough to become correct software is the software, in a worse notation.
A good engineer fills the gaps: talks to the principals, trusts a hunch, asks the question nobody wrote down. A model fills gaps too. Sometimes it asks. Sometimes it grows a third arm.
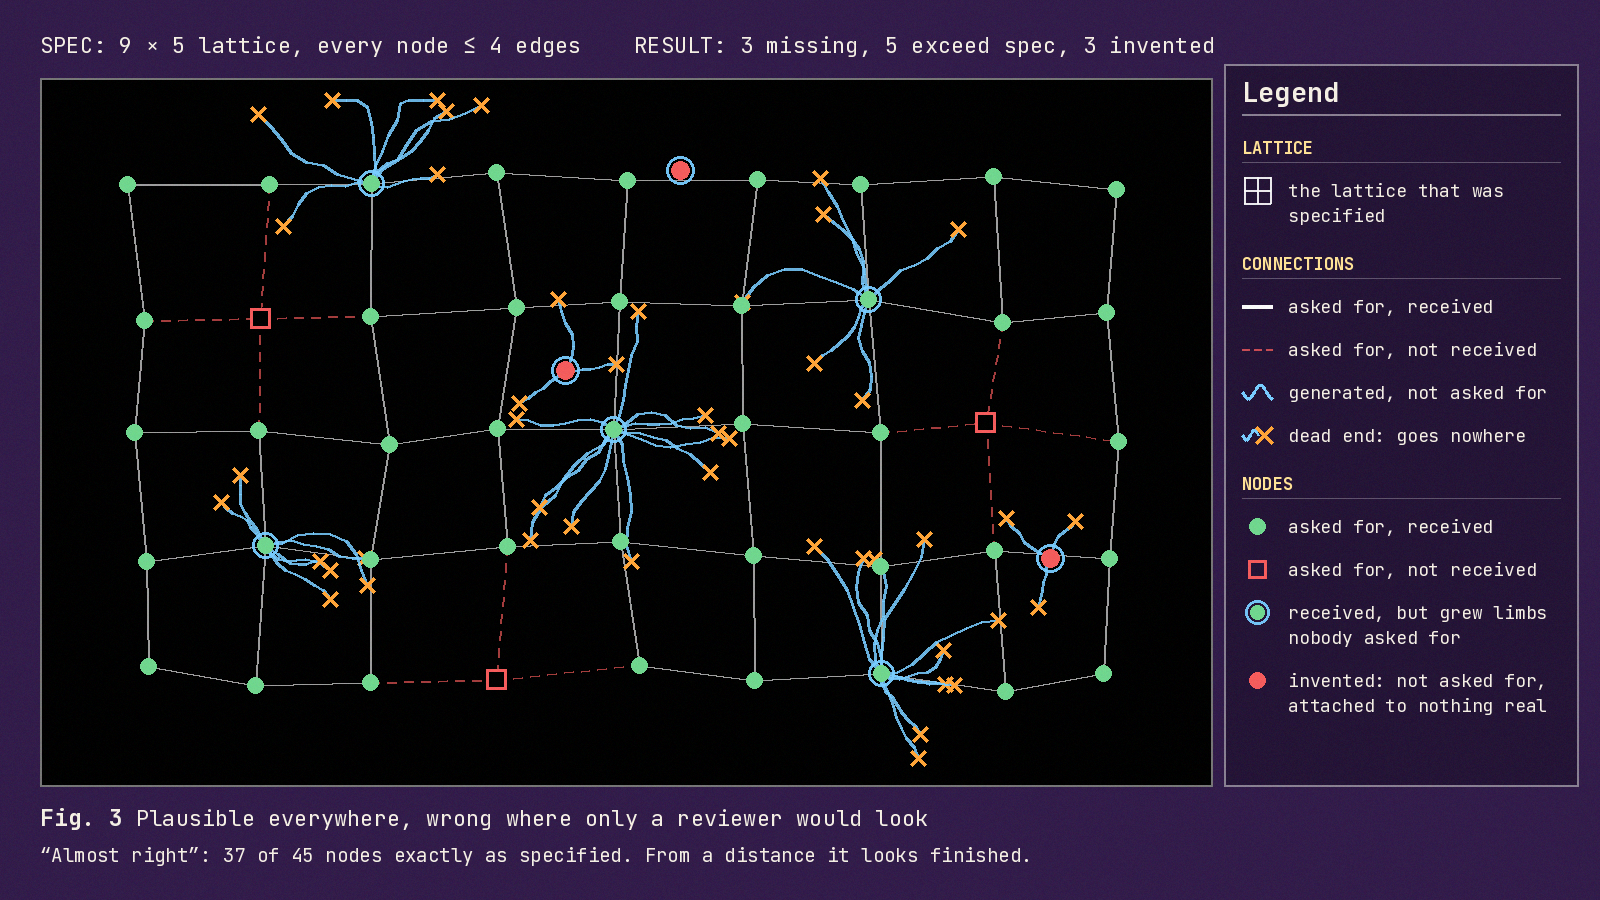
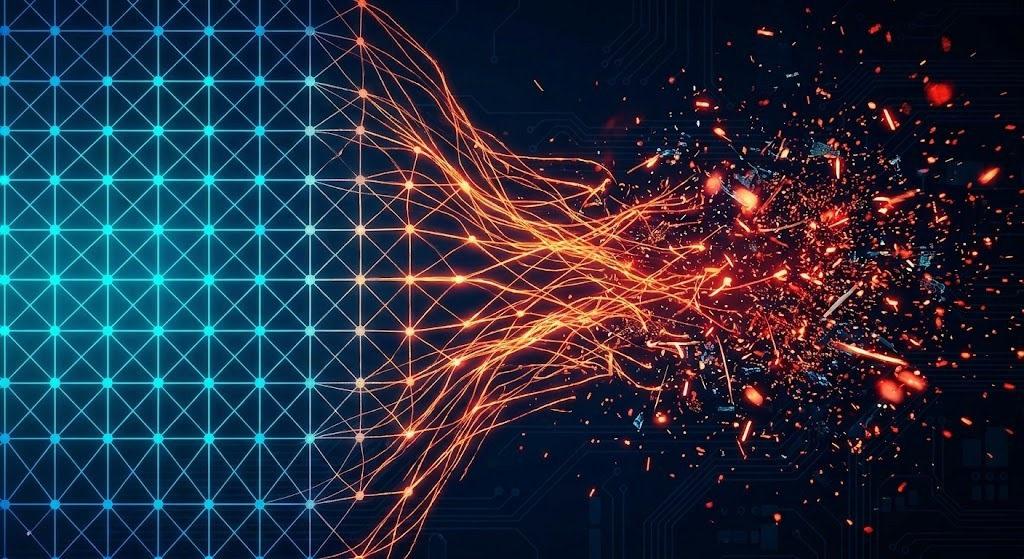
Fig. 2: The third arm. A simulation of a poorly implemented AI solution: A 9×5 grid where every node connects to at most four neighbors.
🌈️ Autonomy is a spectrum, not a switch
None of this is an argument for less AI. It’s an argument for AI with people who understand it in charge. The question was never “automate or don’t.” It’s how much judgment the task needs, and who supplies it.
| Rung | The model… | A person… | Move right when… |
|---|---|---|---|
| In the loop | proposes | decides, every time | reviewers rarely override it |
| On the loop | acts | watches the aggregate, steps in | override and incident rates hold steady on your work |
| Autonomous | acts alone | audits now and then | the record, on your own data, says it’s earned |
To pick a rung, ask three things. Can you undo it? How far does a mistake travel? Can your reviewer tell right from plausible in a minute or less? Run that opening team’s request handler through them and the answer is obvious: the design belonged in the loop, and only the boilerplate had earned a looser leash.
It runs both ways, too. If a task has a bad month, move it back left. That’s not failure, that’s a Tuesday.
“Earned” means measured, over time, on your own work, not on the vendor’s benchmark. Track the numbers vendors don’t publish: duplication, churn, coupling, stability, review load. If AI is helping your codebase, those will say so first, well before the incident report does. And every human override is labeled training data from your own experts. Keep it. It’s the most valuable data you own, and it only exists while those experts are still in the room.
That’s also why hiring matters. “Uses AI” describes everyone. Understanding how the model works, and noticing when it’s wrong, is the scarce part. (Interview tip: ask for a time the model was wrong, then watch their face.) The model doesn’t remove the work. It moves it from writing to reviewing, and reviewing takes someone who knows what good looks like.
🛠️ Build better systems with AI
🧯 Right-size the model
- Reach for the algorithm first. If a plain algorithm, or a homegrown, public or purchased ML model, can solve it, an LLM is overkill. You get deterministic results, better performance and a smaller bill. Save the LLM for when you really need one, like generative work or a chat interface over a customer knowledge base.
- Right-size the model, and consider on-prem. Most business work doesn’t need a genius in a hyperscale data center. It needs a clerk who doesn’t make things up. A small model on a box you own keeps the data home, keeps the bill flat and sips power instead of guzzling it.
⌨️ When writing code
Don’t forget how to code. Skills wane, and judgment goes with them. Generating code feels productive right up until something breaks, and then fixing it (or coaxing the model into fixing it) is like chewing rocks. Use AI as a reference; it’s excellent at researching algorithms, libraries, services and where each should run. Know the fundamentals, like data structures, database design, refactoring and minimal dependencies, because the model knows them too and you need to know when it’s wrong. Learn the design patterns and the anti-patterns, and remember the golden hammer from the era when we tried to solve everything with a pattern.
A few principles have outlived every framework fad: separation of concerns, DRY, loose coupling and high cohesion, YAGNI, fail loudly, and make it work, make it right, make it fast, in that order. None of them is about typing. That’s the point.
🤝 Working with agents
An agent is an LLM with tools, a loop and a job description. I once handed a crew of them a real service, pages of house rules, and instructions to check each other’s work. What came back compiled, passed its own tests, and needed a rewrite. What’s held up since:
- One agent, one job. Separation of concerns applies here too: a planner, an implementer, a test writer, a reviewer, each with its own instructions, tools and only the context its job needs. An agent that designs, builds, tests and judges its own work grades itself, and it’s generous.
- Agent review is a pre-filter, never the review. A reviewer agent with a different brief catches the mechanical stuff: the missing test, the leaked credential, the rule it was told to check. It won’t catch a wrong boundary, a schema the model quietly worked around, or a third arm. Those need someone who holds the standard.
- Skills over prompts. Put how you do things (the review checklist, the migration recipe, the house style) in versioned skill files the agent loads when the task matches. Treat them like code: in the repo, reviewed, tested.
- Few, concrete, enforced rules. The rules that got ignored said “Always” and “Never.” The ones that hold are short, specific (“one class per file, one return point,” not “write clean code”), stated once where every agent reads them, and checked by something that isn’t the model: a linter, a dependency rule, an architecture test, a coverage gate. Don’t ask an agent to honor DRY; give it the duplication detector that fails when it doesn’t. And put a human on the cases where “most of the time” isn’t good enough.
- Small tasks, short loops. One task, one change, reviewed before the next. Drift compounds with context length, and nothing in Fig. 1 happens in a two-hundred-line pull request.
🏁 Conclusion
Back to that team. The code wasn’t wrong and the tool wasn’t broken. What was missing was someone standing at the right spot on the spectrum, with enough scar tissue to say “not like that.” We built a machine that produces plausible software faster than anyone can check it, so I’d keep the checkers, and let them decide how long the leash is.
Try this Monday: pick one task your team gives a model today and decide which rung it’s on. If you can’t say, that’s your finding.